
Stockroom
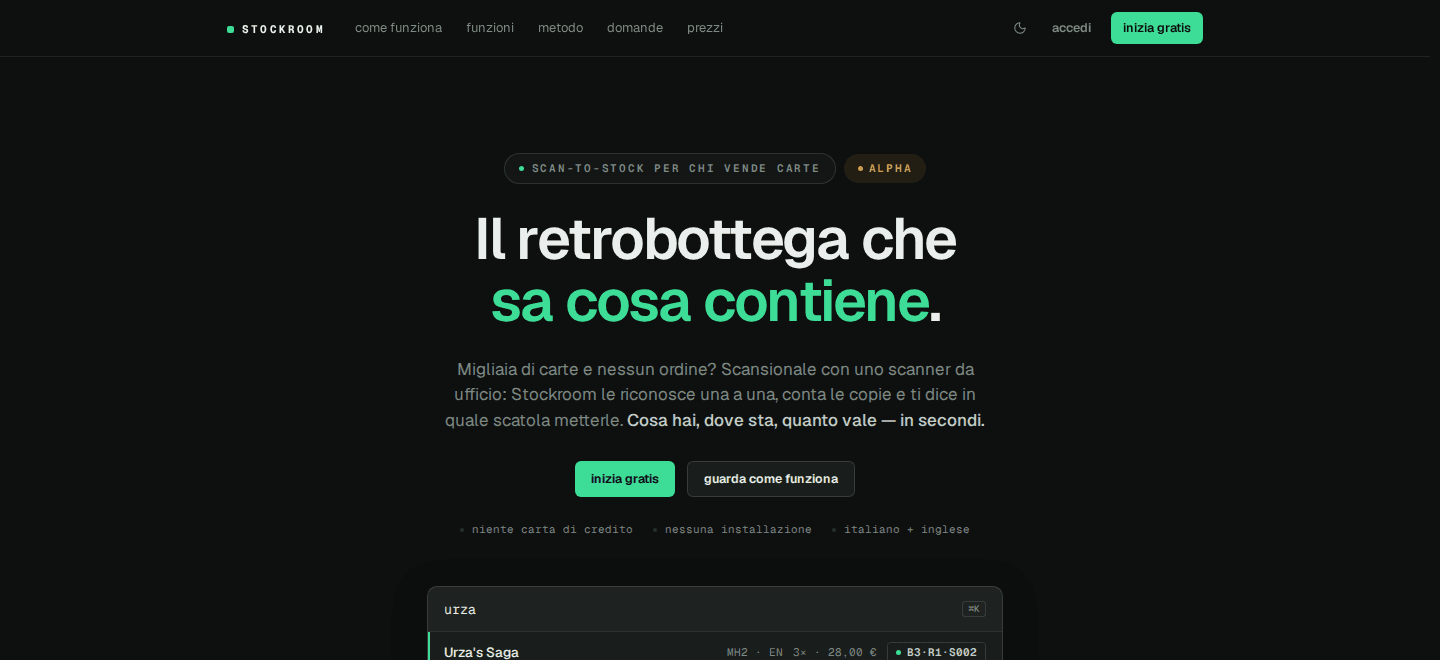
Stockroom is inventory software for trading card shops, live in alpha and starting with Magic: The Gathering. A shop scans its bulk with the scanner it already has, drags the images into the browser, and Stockroom recognises every card, counts the copies and puts them on a shelf.
Visit stockroom.gg ↗- cards resolved in the first production run
- 112/113
- vector lookup after one query fix
- 2 s → 1.6 ms
- estimated cost per 1,000 cards
- < €2
The problem
A shop that buys bulk doesn't really know what it owns or where it is. Cataloguing thousands of cards by hand takes hours per thousand, so nobody does it, and when a customer asks for a card the answer is "maybe, come back tomorrow".
Three steps, cheapest first
The browser crops each card and reads the line printed at the bottom with OCR, set code and collector number, so the first step costs nothing on the server. If that line is readable the card is found with a plain lookup.
If it isn't, an embedding of the image is compared against about 106,000 printings in Postgres with pgvector. A clear match is accepted. When two printings are close, the operator picks between two or three candidates.
Only what's left goes to a language model, and it can only choose from that closed list of candidates. It never invents a card. If the model is switched off the work doesn't stop, the operator just picks more often. The same pipeline started on Dashi, where it had already processed about 25,000 cards.
Being honest about accuracy
Shops scan on their own, so nobody knows the right answer for every card and top-1 accuracy can't really be measured. The goal I picked instead is something a shop can feel: the operator should touch fewer than one row in five. Every correction is saved, so the mistakes become a labelled dataset to tune the thresholds on.
A 1,000x fix
Early on, the similarity search took around two seconds, with spikes of ten. The query was written in a way that skipped the vector index and scanned the whole catalogue. Rewritten to sort on distance, the same lookup takes 1.6 ms with a warm cache, and recall checked out the same.
Stack
Next.js · Postgres · pgvector · Drizzle · Better Auth · tesseract.js · AI SDK